Tenant-scoped · read-only · bounded
Evidence MCP for AI assistants
PackDB's MCP server lets an AI client retrieve scoped observability evidence without giving it write access, a tenant selector, or an open-ended query surface. This is an external evidence channel, not the PackDB Investigator.
Setup is available
The development target at https://api.dev.packdb.cloud/api/mcp has a recorded supported-client authorization and evidence witness. Follow the setup below for that exact resource.
PackDB remains default-off globally. Discovery is authoritative for every other target; this certification does not enable or certify them.
Pinned contract
Endpoint and transport
Stateless Streamable HTTP at <configured-prefix>/api/mcp, pinned to MCP protocol 2025-11-25. It accepts JSON-RPC over POST; GET, server events, resumability, and MCP sessions are not part of this profile.
Dedicated authorization
Every request needs a bearer token whose audience/resource is the target's canonical MCP endpoint and whose scope includes packdb:evidence:read. A missing or invalid credential returns 401; a valid token without the scope returns 403.
Server-resolved tenant
PackDB resolves the tenant server-side from the verified user principal. Tool arguments and request headers cannot supply or override a tenant or platform organization ID.
Fail-closed deployment
The route is absent when disabled. Enabled public targets require TLS, a configured public origin, authorization metadata, and a token-verification boundary that agrees on the same canonical resource URI.
Advertised tools
The current server advertises exactly 14 names in tools/list. 12 have direct backing providers and 2 require a configured watch source. That does not mean a particular target has enabled MCP, runs this catalogue, or has every backing data source.
Readiness
get_readinessPoint-in-time PackDB readiness evidence, including explicit missing smoke evidence when it is unavailable.
Metrics
query_metricsTyped metric filters, aggregation, grouping, and response limits over an absolute time window.
Service RED metrics
get_service_red_metricsComplete request-count and duration increases for one service over an absolute time window. Missing identities, sparse coverage, or a partial scan fail the call rather than becoming healthy zeroes.
Service error logs
get_service_error_log_summaryComplete error and fatal log groups for one service over an absolute time window, as message fingerprints, counts, and latest timestamps with log bodies withheld. A reached bound or a partial scan fails the call rather than truncating it.
Service spans
get_service_spansA complete span census for one emitting service over an absolute time window, keeping only exact peer-service and error-type facets. A reached bound or a partial scan fails the call rather than truncating it.
Logs
query_logsTyped, service-scoped log evidence over an absolute time window with enforced response bounds.
Trace search
search_tracesA bounded trace sample selected by typed filters and an absolute time window.
Trace by ID
get_traceA bounded lookup of one trace by its trace ID.
Service graph
get_service_graphService-graph evidence derived from a bounded trace window and reported with its sampling limits.
Service neighborhood
get_service_graph_neighborhoodThe complete one-hop dependency neighborhood of one service over an absolute time window. A reached bound or a partial scan fails the call rather than becoming a sampled or tenant-wide graph.
GenAI reliability
get_genai_reliabilityTenant-wide GenAI operation counts and ratios over an absolute time window. No prompt or response body, and no producer-authored string such as a provider or model name, is returned.
Service GenAI reliability
get_service_genai_reliabilityThe same GenAI counts and ratios for one named service. It is a separate tool, so the scope a caller gets never depends on an omitted argument.
Changes
list_changesBounded canonical change events over an absolute time window; requires a configured watch source and otherwise refuses with typed not_configured.
Watch result
get_watch_resultOne sealed watch result selected by immutable run ID; requires a configured watch source and otherwise refuses with typed not_configured.
list_changes requires a configured watch source. Without one, it returns typed unsupported_provider with reason not_configured rather than empty evidence.
get_watch_result requires a configured watch source. Without one, it returns typed unsupported_provider with reason not_configured rather than empty evidence.
On the certified target, the shared watch source passed its server-owned credential and tenant-bound read preflight on 2026-09-15. Both source-dependent calls then passed the supported-client supplement on 2026-09-15: a bounded change list and a typed missing watch-result envelope. Other targets still require their own source and witness.
The current certification attempt recorded a target-level typed acquisition failure for get_service_red_metrics. This target is marked degraded; those failed calls are recorded separately from successful witnessed evidence.
The certified target's records witnessed 8 of these tools, with packdb.mcp.evidence.v2 envelopes. No recorded witness covers get_readiness, query_logs, search_traces, get_trace, or get_service_graph yet, so the certification does not extend to them.
Bounded evidence
Query tools accept typed investigation fields: absolute time windows, filters, grouping or aggregation, and response limits. PackDB lowers those fields to its bounded query plans. Raw SQL, PromQL, LogQL, TraceQL, and serialized plans are not accepted as MCP tool input.
Successful results use evidence schema packdb.mcp.evidence.v2 and report the source surface, exact window, query identifier or parameters, limits and consumption, freshness, missing or partial evidence, evidence authority, applicable privacy state, and the evidence_links replay-link field. That field stays an empty list while replay is withheld. Execution ceilings are reported separately from response caps; an unenforced ceiling stays explicit.
A sampled, truncated, partial, or advisory result cannot be turned into a confident absence claim. Provider failures are typed tool errors rather than empty evidence.
A capability that is absent on the target is reported as unsupported_provider with a typed reason. The field replaced a v1 boolean that could not tell an unattached source from a capability nothing implements:
explicitly_disabled— an operator turned the capability off. It is the only reason a client may show as skipped.not_configured— the capability exists, but this deployment has not attached its backing source.not_implemented— nothing implements the capability, so no configuration can supply it.
None of these reasons supports an absence claim.
These current envelope fields sit inside the top-level evidence object:
schema_versionsource_surfacewindowquerybudgetexecution_limitsfreshnessmissing_evidenceevidence_authorityevidence_authority_detailprivacy_stateevidence_linksexecution_limits, evidence_authority_detail, and privacy_state are conditional on the backing surface and inputs; the other fields are always present.
Evidence-first prompts
Good prompts against this surface ask for evidence with explicit bounds, and good answers cite the deterministic query metadata that came back — the exact window, the typed query, the limits that applied, and any gaps — instead of asserting causes the evidence cannot carry.
Observation counts across an exact window
query_metricsPrompt: “Using query_metrics, count observations for metric http_requests_total from 2026-08-27T13:00:00Z through 2026-08-27T15:00:00Z at 60-second steps; compare 13:00-14:00Z with 14:00-15:00Z. Set max_rows=500, max_series=50, and max_bytes=262144. Use lower caps if my plan or read-only role requires them.”
A grounded answer compares only the returned 60-second buckets, names the typed count operation and both absolute subwindows, reports the caps and consumption for each call, and identifies any partial or missing evidence instead of presenting an incomplete comparison as complete.
Cites window, query, budget, freshness, missing_evidence.
Reset-aware counter rate
query_metricsPrompt: “Using query_metrics, calculate the reset-aware per-second counter rate for metric http_requests_total field value from 2026-08-27T14:00:00Z through 2026-08-27T15:00:00Z with 60-second steps and a 300-second lookback. Set max_rows=500, max_series=50, and max_bytes=262144. Use lower caps if my plan or read-only role requires them.”
A grounded answer states the exact window, step, lookback, typed counter-rate operation, response caps, and freshness. It reports any unenforced execution ceiling or missing evidence rather than turning a bounded result into a complete-traffic claim.
Cites window, query, budget, execution_limits, freshness, missing_evidence.
Bounded service error-log groups
get_service_error_log_summaryPrompt: “Using get_service_error_log_summary, summarize error and fatal log groups for canonical service payments from 2026-08-27T09:25:00Z through 2026-08-27T09:35:00Z. Set max_groups=100 and max_bytes=262144. Use lower caps if my plan or read-only role requires them.”
A grounded answer summarizes only the returned fingerprints, counts, and latest timestamps inside the stated service and window, quotes the enforced bounds, and reports missing evidence instead of treating a partial scan as complete.
Cites window, query, budget, missing_evidence.
Bounded service span census
get_service_spansPrompt: “Using get_service_spans, return the complete span census for canonical service checkout from 2026-08-27T14:00:00Z through 2026-08-27T15:00:00Z. Set max_spans=2000 and max_bytes=262144. Use lower caps if my plan or read-only role requires them.”
A grounded answer describes only the returned span census and its exact service and window, quotes the enforced span and byte bounds, and reports a reached bound or partial scan as missing evidence instead of presenting it as complete.
Cites window, query, budget, execution_limits, missing_evidence.
Ungrounded — do not publish this
“The root cause is connection-pool exhaustion in the checkout service; deploying a pool-size increase will fix it.”
Grounded — cite the evidence and its bounds
“Within 2026-08-27T14:00-15:00Z, error logs for service=checkout matching “pool timeout” rose from 0 to 214 rows (response bound 500, not truncated), and the trace sample over the same window shows checkout→payments spans waiting on connection acquisition. Evidence is bounded to this window and sample; causes beyond it are unverified.”
Do not ask an assistant for a PackDB replay link yet: evidence_links stays an empty list while create_evidence_link is withheld, so any link an assistant produces did not come from PackDB.
Audit posture
Query work retains an MCP entrypoint classification, while each response carries provenance, query fingerprint or parameters, budget use, authority, freshness, and missing-evidence context. Bearer credentials are consumed at the boundary and are not passed to downstream query services. The current contract does not promise a customer-visible historical audit-log product.
Prompt and content boundary
Telemetry text is evidence, not an instruction that can change authorization, budgets, or server behavior. Raw prompt and response bodies are not returned. The GenAI reliability tools return counts and ratios only, with no producer-authored string such as a provider, model, or error-type name.
Do not reuse an ingest API key
A PackDB machine key such as packdb_… sent through X-API-Key is for collectors, Grafana, and machine query surfaces. It is not an MCP credential. A browser session token is not interchangeable either. An MCP client uses only the dedicated, resource-bound user bearer described above.
Connect to the certified target
These instructions connect a supported remote-MCP client to the exact development resource certified on . The client discovers the authorization server from PackDB; you do not paste or manage a bearer token.
{
  "mcpServers": {
    "packdb-dev": {
      "type": "http",
      "url": "https://api.dev.packdb.cloud/api/mcp"
    }
  }
}- 1Save the configuration above as
.mcp.jsonat the root of the project where you will use the assistant. - 2Start the client from that project and approve its browser sign-in. Choose the intended workspace and consent to the read-only
packdb:evidence:readscope. - 3Confirm the client lists the PackDB tools, then start with one of the bounded, witnessed examples below.
Never put an ingest API key, browser session, authorization code, access token, refresh token, or PKCE verifier in the project file. The browser authorization flow issues the resource-bound credential directly to the client.
What the certified state looks like
Your workspace reports MCP availability in two places, both reading the same probe: the Connect page's AI assistants card and the readiness centre's MCP check.
These are fixture images, not connection evidence. They show the interface state derived from the contract mirror; they do not show an MCP session.
The live evidence is the redacted supported-client record at docs/certification/mcp-dev-supported-client-2026-09-15.md and the watch-call supplement at docs/certification/mcp-dev-watch-source-supported-client-2026-09-15.md. Those records, rather than these images, certify the target and calls. No credential, token, telemetry value, tenant identifier, prompt, or response body appears in either image.
Settings → Connect
Fixture UI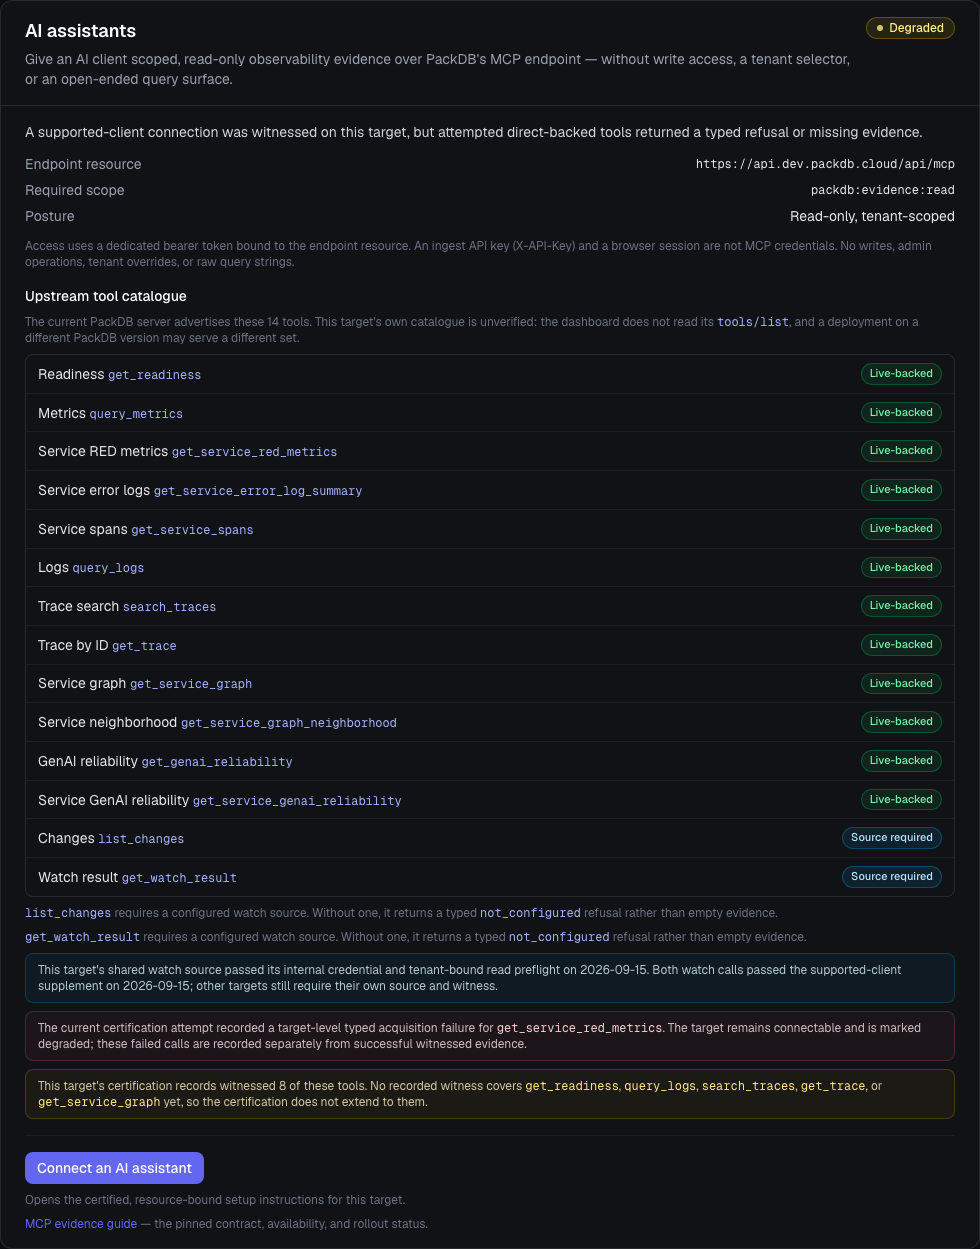
The AI assistants card for the currently certified dev target: the endpoint resource, read-only scope, upstream tool catalogue, eight successfully witnessed tools, the separately degraded service RED metrics read, and five other names outside the current claim. The connect control is enabled only for the certified resource.
Readiness centre
Fixture UI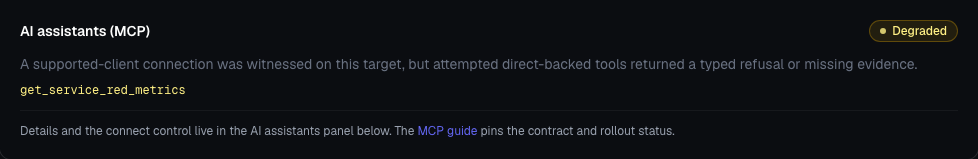
The same degraded availability, rendered as a readiness dimension. Both surfaces read one probe, so they cannot disagree about the target.
Withheld tools
These names are intentionally absent from tools/list. They are unavailable, not hidden features.
create_evidence_linkWithheldDurable tenant-bound replay storage, authenticated redemption, and an end-to-end mint-and-redeem witness.
Not in scope
- Writes, alert mutations, or remediation execution
- API-key creation, billing changes, or admin operations
- Arbitrary SQL or model-authored query strings
- Tenant or organization overrides
- Support impersonation or support-bundle generation
- AI-generated root-cause or prevention claims
Related guides
- Quickstart — send telemetry before retrieving evidence.
- Grafana — configure machine query access with a separate credential.
- Troubleshooting — understand unavailable, 401, and 403 states.